The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →NVIDIA Blackwell’s FP4 advance is not simply a switch from 16-bit numbers to 4-bit numbers. The useful combination is NVFP4 arithmetic, fine-grained scaling, Blackwell Tensor Cores, stochastic rounding, outlier handling, and software that decides which parts of a model can safely use lower precision.
That combination is the foundation of what NVIDIA calls Blackwell’s second-generation Transformer Engine. It is designed primarily to make large-language-model and mixture-of-experts training and inference faster and less memory-intensive. For gamers and creators, the consumer RTX 5090 makes some of Blackwell’s FP4-oriented AI capability available in a desktop, but it is not equivalent to a B200, GB200, or DGX B200 system.
As an Amazon Associate I earn from qualifying purchases.
NVIDIA Blackwell’s FP4 advance is not simply a switch from 16-bit numbers to 4-bit numbers. The useful combination is NVFP4 arithmetic, fine-grained scaling, Blackwell Tensor Cores, stochastic rounding, outlier handling, and software that decides which parts of a model can safely use lower precision.
That combination is the foundation of what NVIDIA calls Blackwell’s second-generation Transformer Engine. It is designed primarily to make large-language-model and mixture-of-experts training and inference faster and less memory-intensive. For gamers and creators, the consumer RTX 5090 makes some of Blackwell’s FP4-oriented AI capability available in a desktop, but it is not equivalent to a B200, GB200, or DGX B200 system.
#1 Best Overall
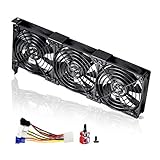
- 3 x 92mm fans combined into one interface, can be connected to the motherboard's 3-pin or 4-pin interface and you only need to access one interface to run all the fans
- This cooling fan's total size is 11in(L) x 4.72in(W) x 1.18in(H), designed for most universal graphic card video card VGA cooling,just please check the size to make sure your pc has enough space
- D-type interface cable included four interfaces, three voltages: 5V, 7V and 12V; different voltages with different airflow, speed and noise. You can select the appropriate voltage interface to start the fan
- The double ball bearing has a service life of 65,000 hours, and the 7 blades produce strong airflow to keep the computer case cool
- packing list: 3 x 92mm fans (PCI bracket screwed), 1 x multi-voltage cable ,1 x mini screwdriver,1 x fixing screw
Why lower precision matters for AI
Transformer models are constrained by three related problems: the amount of computation required for matrix multiplication, the bandwidth needed to move weights and activations, and the memory required to store the model while it runs.
Using fewer bits can help with all three. A 16-bit value requires four times as much payload storage as a 4-bit value, and lower-precision Tensor Core operations can process more values per unit of hardware than higher-precision operations. Smaller data also means less movement between memory and the compute units.
The difficulty is numerical range. A neural network tensor may contain a mixture of very large and very small values. A compact format has fewer representable values and less room for outliers, so a naïve conversion can erase useful information or introduce enough error to damage model quality.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Blackwell’s approach is therefore not just make every value FP4. It uses a small FP4 payload together with scaling metadata and model-specific rules for applying that payload.
What FP4 and NVFP4 actually mean
FP4 is a four-bit floating-point format. NVIDIA’s documented NVFP4 format uses an E2M1 layout:
- one sign bit;
- two exponent bits; and
- one mantissa bit.
The raw four-bit value can represent magnitudes up to approximately plus or minus 6. That is useful as a compact numerical payload, but it is not enough dynamic range to represent an entire neural-network tensor accurately by itself.
NVFP4 addresses that limitation with hierarchical scaling. In the documented implementation, a local FP8 E4M3 scale is shared by each block of 16 consecutive elements, while a global FP32 scale applies to the tensor. Conceptually, reconstruction looks like this:
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →reconstructed value ≈ FP4 value × local block scale × global tensor scale
The FP4 number supplies the compact detail; the scales act like rulers that expand or contract that detail to match the range of the values around it.
The ruler analogy
Imagine measuring every object in a warehouse with one ruler. The ruler must be long enough for the largest object, but it will be imprecise for tiny objects. That is similar to using one scale for an entire tensor: an outlier can force the scale to accommodate it, leaving ordinary values with too little useful resolution.
NVFP4 instead gives small groups their own rulers. A block containing small values can use a small scale, while a block containing larger values can use a larger one. The global scale keeps those local measurements aligned with the tensor as a whole.
Rank #2

- 2 x 92mm fans combined into one interface, can be connected to the motherboard's 3-pin or 4-pin interface and you only need to access one interface to run all the fans
- This cooling fan's total size is 7.36in(L) x 4.72in(W) x 1.18in(H), designed for most universal graphic card video card VGA cooling,just please check the size to make sure your pc has enough space
- D-type interface cable included four interfaces, three voltages: 5V, 7V and 12V; different voltages with different airflow, speed and noise. You can select the appropriate voltage interface to start the fan
- The double ball bearing has a service life of 65,000 hours, and the 7 blades produce strong airflow to keep the computer case cool
- packing list: 2 x 92mm fans (PCI bracket screwed), 1 x multi-voltage cable ,1 x mini screwdriver,1 x fixing screw
Why block size and layout matter
Fine-grained scaling improves numerical behavior, but it adds metadata, layout rules, and work for the quantization and matrix-multiplication kernels. NVFP4 is therefore not literally four bits per parameter in total storage. The values use four-bit payloads, but the local and global scales also consume memory.
NVIDIA’s current Transformer Engine recipe uses different scaling layouts depending on the tensor:
| Tensor or use | Documented NVFP4 treatment | Why it matters |
|---|---|---|
| Activations | Generally one-dimensional blocks of 16 elements | Provides a separate scale for nearby values instead of forcing one scale across the whole tensor. |
| Gradients | Generally one-dimensional blocks of 16 elements | Works with stochastic rounding during training to reduce systematic quantization bias. |
| Weights | Can use two-dimensional 16-by-16 scaling in the current recipe | Helps preserve more consistent behavior when the weight matrix is used in rowwise and columnwise operations. |
| Whole tensor | A global FP32 scale | Provides a shared reference for the local block scales. |
This is why claims such as Blackwell stores every model at exactly one-quarter the memory are too simple. The payload can be dramatically smaller, but scale tensors, padding, alignment, temporary buffers, framework behavior, and the parts kept in higher precision all affect actual memory use.
What NVIDIA means by the second-generation Transformer Engine
The Transformer Engine is both hardware-assisted technology and a software library. In NVIDIA’s description, Blackwell’s second-generation Transformer Engine combines custom Blackwell Tensor Core technology with software innovations in TensorRT-LLM and NeMo for large-language-model and mixture-of-experts workloads.
The software component is not merely a driver toggle. NVIDIA describes Transformer Engine as a library of optimized Transformer building blocks with Python and C++ interfaces and automatic-mixed-precision-like APIs. It supports major frameworks including PyTorch and JAX. On Blackwell, the documented library supports FP8 as well as MXFP8 and NVFP4.
In practical terms, the engine helps coordinate several decisions:
- which tensors use FP4, FP8, or a higher precision;
- how local and global scales are calculated and stored;
- how tensors are laid out for the hardware kernels;
- how rounding is performed; and
- which operations need special treatment to preserve model accuracy.
That coordination is the reason “second-generation Transformer Engine” should not be read as the name of one isolated circuit. The Tensor Cores provide the fast arithmetic, while the software stack makes that arithmetic usable in real Transformer implementations.
How Blackwell makes FP4 more practical
1. Fine-grained scaling reduces the outlier problem
Traditional per-tensor scaling uses one scale factor for an entire tensor. If one value is unusually large, the scale must protect that value. Smaller values may then be rounded too aggressively or become effectively indistinguishable.
Blockwise microscaling reduces the range that each scale must cover. Groups of 16 elements can be represented according to their local distribution rather than the distribution of the entire tensor. This does not make FP4 lossless, but it gives the four-bit payload a much better chance of preserving useful information.
2. Stochastic rounding limits systematic bias
Ordinary rounding always chooses the nearest available value. Repeated across billions of values, a consistent rounding direction can introduce bias. NVIDIA’s documented NVFP4 training recipe uses stochastic rounding for gradients, choosing between nearby representable values according to their probabilities.
Blackwell also includes hardware acceleration for stochastic rounding. The goal is not to make each individual rounded value exact; it is to reduce the tendency for quantization errors to accumulate in one direction during training.
Rank #3
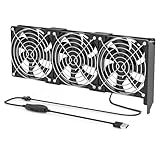
- 【Durable & Compact Design】This cooling fan is built with high-quality materials for enhanced durability. Its compact size makes it easy to install in tight spaces, providing reliable active cooling for graphics cards or server components
- 【Broad Compatibility for High-Performance Hardware】Ideal for graphics cards and other server hardware that require additional cooling. Perfect for use in consumer chassis with limited airflow to improve system stability and performance
- 【Adjustable Fan Speed for Custom Airflow】With a speed range of 1500–3000 RPM, the fan allows you to fine-tune airflow based on your cooling needs. Whether you prioritize silent operation or maximum cooling, this fan gives you full control
- Flexible Power Options with USB & 4-Pin Support】Comes with a USB to 4-PIN PWM cable for easy 12V power connection. The fan can be turned on or off manually, offering flexible control
- 【Complete Kit, Ready to Install】Includes 1 x cooling fan, 1 x USB to 4-PIN cable, and 1 x mounting screw. Everything you need for a quick and hassle-free installation—no additional parts required
3. Hadamard transforms help smooth outliers
NVIDIA’s NVFP4 training recipe also documents random Hadamard transforms. Their purpose is to redistribute unusually large values so that the tensor’s distribution is easier to represent with a low-precision format.
Recommended Free Tools
This is an important distinction: the model may need a transformation step before quantization, not just a different numeric data type. The transform, scaling, rounding method, kernel implementation, and model architecture all become part of the recipe.
4. Sensitive operations can remain above FP4
Production low-precision systems do not have to use FP4 for every tensor. NVIDIA’s documentation recommends keeping particularly sensitive final layers in a higher precision such as MXFP8 rather than assuming that the entire network should run in NVFP4.
This mixed-precision approach is a feature, not a failure. Some layers tolerate aggressive compression well; others are more vulnerable to small numerical changes. The best result may use FP4 for much of the workload, FP8 or MXFP8 for sensitive sections, and still higher precision for selected calculations.
What the Blackwell hardware contributes
NVIDIA says the Blackwell architecture contains 208 billion transistors and two reticle-limited dies connected by a 10 TB/s chip-to-chip link. Its Tensor Cores are designed to execute the low-precision matrix operations that Transformer workloads depend on, while the surrounding architecture feeds those cores with data and handles the required scaling and conversion work.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Repair Windows errors before they cause bigger problems3Scan for outdated or missing drivers - takes under a minuteNVIDIA’s architecture material describes FP4 as enabling roughly twice the performance and roughly twice the model size that can fit in memory. Those are vendor-level architectural claims, not a guarantee that every model, kernel, or application will see the same multiplier. Actual results depend on batch size, sequence length, model architecture, memory traffic, software versions, and how much of the workload can use FP4.
The data-center Blackwell family includes products such as the B200, GB200, DGX B200, HGX B200, and GB200 NVL72, along with later Blackwell-family systems. These products combine GPUs with high-bandwidth memory, host CPUs or networking, and system-level interconnects designed for large model workloads.
For scale, NVIDIA says a DGX B200 combines eight Blackwell GPUs with 1,440 GB of total GPU memory and 64 TB/s of HBM3e bandwidth. That is a fundamentally different class of machine from a desktop graphics card, even though both carry the Blackwell name.
What FP4 means for the GeForce RTX 5090
The GeForce RTX 5090 is the consumer-facing Blackwell product most relevant to enthusiasts who want to experiment with local AI. NVIDIA identifies its GPU as GB202. The card has 32 GB of GDDR7, 21,760 CUDA cores, fifth-generation Tensor Cores, and support for FP4-oriented AI features.
Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minutePC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11For a local workstation or gaming desktop, the NVIDIA GeForce RTX 5090 graphics card can make AI image generation and other supported inference workloads more accessible without renting a data-center machine. NVIDIA has published a consumer example in which FP4 image generation on an RTX 5090 uses less memory and completes faster than an FP16 comparison on an RTX 4090.
That example should be read as NVIDIA’s stated result for that workload and software configuration, not as a universal performance ratio. A model must actually support the relevant FP4 path, and different applications may use FP4, FP8, FP16, or a mixture of formats.
Rank #4
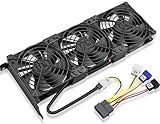
- Package include: 1 Piece Graphic Card Fans ( 3-Fans connected ) with 1*Power D-type Interface cable
- Dimension: 92mm(L) x 92mm(W) x 25mm(H) / 3.62in(L) x 3.62in(W) x 1in(H) in per fan. Totally Size: 276mm(L) x 120mm(W) x 30mm(H) / 10.86in(L) x 4.72in(W) x 1.18in(H)
- Rated Voltage: DC 12V; Rated Current: 0.45Amp; Rated Speed: 3x 1800 RPM; Air flow: 3x 39.8 CFM; Noise: 3x 24.8 dBA
- D-type interface cable included four interfaces, three voltages: 5V 7V and 12V; Different voltages with different airflow, speed, and noise. you can select the appropriate voltage interface to start the fan.
- 3 fans combined into one interface, Can be connected to the motherboard's 3-pin or 4-pin interface and you only need to access one interface to run all the fans.
RTX 5090 versus B200 and GB200
| GeForce RTX 5090 | B200, GB200, or DGX-class Blackwell | |
|---|---|---|
| Primary audience | Consumers, enthusiasts, creators, and local AI users | Cloud providers, research organizations, and enterprise AI deployments |
| Memory | 32 GB of GDDR7 on the RTX 5090 | Much larger system-level memory configurations and high-bandwidth HBM-based designs |
| System design | One desktop add-in card, subject to PC power, cooling, and clearance limits | Multi-GPU systems with specialized networking, cooling, and interconnects |
| Best fit | Local inference, image generation, development, and supported creator tools | Large-model training, large-scale inference, and production clusters |
The RTX 5090 exposes relevant Blackwell hardware, but it does not provide the memory capacity, multi-GPU topology, system bandwidth, or enterprise qualification of a B200 or GB200 deployment. A desktop card can be an excellent local AI tool without being a miniature DGX.
Does FP4 make games faster?
Not automatically. FP4 is most directly relevant to AI matrix operations, model inference, and training. A game that does not use a supported low-precision AI workload will not suddenly gain a fixed frame-rate improvement merely because the GPU contains FP4-capable Tensor Cores.
For players, the practical benefits are indirect and application-dependent. Blackwell’s AI hardware may help supported features such as local generative tools, game-development workflows, image creation, voice processing, or other neural-network workloads. Whether a particular game benefits depends on the game engine and the feature’s implementation, not on the GPU specification alone.
For game developers, FP4 may make it more practical to test or deploy certain AI systems locally, especially when memory is the limiting factor. Examples could include smaller local language models for prototyping, asset-generation tools, or other inference tasks, but the application still needs a compatible model, quantizer, runtime, and kernel path.
Software support is part of the specification
NVFP4 support is not a generic capability that can be assumed from the word Blackwell on a product box. NVIDIA’s current Transformer Engine documentation lists NVFP4 execution for Blackwell-class hardware and identifies documented training support beginning at SM 10.0/10.3 and inference support at SM 10.0 or later. Exact support can change as the library develops.
For a real deployment, check these components together:
Free tools Windows power users keep installed
One-click scans. No signup required.
- GPU architecture: confirm that the specific GPU and workload meet the required Blackwell and SM level.
- Transformer Engine version: verify that the desired NVFP4 recipe and operation are supported in the installed release.
- CUDA and framework versions: check compatibility with the selected PyTorch or JAX release.
- Model implementation: a model may require custom kernels, calibration, quantization settings, or selective higher precision.
- Runtime: TensorRT-LLM, NeMo, Megatron Core, and other runtimes may expose different features at different versions.
- Inference versus training: support for one does not automatically imply identical support for the other.
Megatron Core’s configuration documentation identifies NVFP4 as the supported FP4 recipe for Blackwell-plus architectures and exposes options for FP4 parameters and custom quantizer factories. That is a sign that FP4 is becoming integrated into major NVIDIA training infrastructure, but it also highlights the importance of version matching.
NVIDIA’s Transformer Engine release documentation continues to add NVFP4 capabilities, including expanded grouped-GEMM support. Because these features are evolving, deployment teams should check the release notes and compatibility documentation at the time of installation rather than relying on a static feature list.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Who should consider an RTX 5090 for FP4 workloads?
Buy it for local AI if the workload fits in 32 GB
An RTX 5090 is the realistic physical Blackwell option for an enthusiast who wants to run supported AI tools at home. It is most compelling when the workload benefits from fast Tensor Core inference and when a 32-GB local memory ceiling is sufficient.
Check the exact application before buying. Some tools may use FP4 effectively; others may fall back to FP8 or FP16, use a different quantization format, or need more memory than the card provides. The presence of FP4 hardware does not guarantee that every open-source model or consumer application has an optimized NVFP4 implementation.
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Do not buy it solely for the label
If the goal is ordinary gaming performance, compare supported games, resolution, ray-tracing requirements, upscaling and frame-generation behavior, power, cooling, and price. FP4 is an AI capability, not a universal replacement for rasterization or ray-tracing performance.
Best Value

- Ventilation Fan: Designed to quietly ASUS GT/RT- AC5300 , cool Xboxs, CPU/ GPU, Playtations, Rokus, TVs, receivers, mondems, routers, DVRs, window fans ,network appliances, DIY aquarium cooling and other audio video electronics
- Variable Speed Control: 110V - 220V Fan power supply with speed control function, turn the knob to adjust the speed, 4V - 12V adjustable fan speed,and can turn off the fan . | Input: 100V - 240V 50/60Hz | Output: DC 3-12V 200-2000ma
- DIY Vertical Window Fan: Can both vertical and horizontal, provide efficient cooling and ventilation. Mining rigs rely on the cooling power of fans for optimal operation.Double Metal Protective, the fan is equipped with double metal protective net
- Easy to Install: Draw out air in refrigerators, provide ventilation in greenhouses, prevent amplifier overheating, and vent hot air from living room consoles like PS4. Y cable connects 2 fans, two fans can be 42cm/16.5 in far away from each other
- Dual Ball Bearing: 240mm x 240mm x 25mm / 9.45in(L) x 4.72in(W) x 1in(H) in in total. | Rated Voltage :12V | Rated Current: 0.93A at full speed | Airflow: (82CFM)x4 at 12V | Speed: 2500 RPMx4
Plan the rest of the PC
NVIDIA specifies a 1,000 W recommended system power figure for the RTX 5090 and notes that the card requires substantial physical clearance and room around the power connection. Before purchasing, verify the exact board’s dimensions, the case’s GPU clearance, airflow, the power supply’s capacity, and the required PCIe Gen 5 power cabling.
A complete build may therefore require an RTX 5090-compatible power supply and PC case, not just the graphics card. Board-partner models can differ in size and cooler design, so do not assume that clearance for one RTX 5090 model applies to every model.
Use enterprise hardware or cloud access for large models
Training large language models or mixture-of-experts models is a different purchasing decision. B200, GB200, DGX, and similar systems are generally acquired through enterprise or channel sales and are built around multi-GPU memory, networking, cooling, and software qualification. A cloud Blackwell instance may be more practical for occasional experiments, but availability, region, price, and software support must be checked with a current provider.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Clear out junk files and repair common Windows errors3Scan for outdated or missing drivers - takes under a minuteA practical NVFP4 evaluation checklist
- Measure the baseline: record the model’s FP16 or FP8 accuracy, latency, throughput, and peak memory use.
- Identify eligible operations: determine which matrix multiplications and tensors can use NVFP4 in the selected framework and runtime.
- Account for metadata: include local scale tensors, global scales, padding, conversion buffers, and higher-precision layers in the memory estimate.
- Choose the scaling layout: use the documented block dimensions for activations, gradients, and weights rather than applying one generic scale everywhere.
- Handle outliers: test the documented Hadamard-transform approach where the recipe calls for it, and inspect the distribution of sensitive tensors.
- Use mixed precision: keep fragile operations or final layers in MXFP8 or another suitable higher precision when testing shows an accuracy problem.
- Evaluate stochastic rounding during training: especially for gradients, where systematic rounding error can accumulate.
- Test the actual workload: compare quality and speed on the intended sequence lengths, batch sizes, prompts, images, or game-development tasks.
- Pin compatible versions: document the GPU, driver, CUDA, framework, Transformer Engine, model code, and kernel versions together.
Common misconceptions about Blackwell FP4
Misconception: FP4 means the model uses exactly four bits per parameter
Only the payload is four bits. NVFP4 also uses local and global scaling metadata, and real implementations may keep selected layers or operations in higher precision.
Misconception: every Blackwell GPU has identical Transformer Engine behavior
Blackwell products share an architectural family, but the RTX 5090, B200, GB200, and DGX systems differ in memory, interconnects, power, software qualification, and intended workloads. The supported operations and performance depend on the specific GPU and software stack.
Misconception: FP4 eliminates quantization loss
Scaling, stochastic rounding, Hadamard transforms, and selective higher precision reduce the risks of low-precision computation. They do not make quantization mathematically lossless, nor do they guarantee equal quality for every model.
Misconception: NVIDIA’s headline multiplier applies to every game or AI tool
NVIDIA’s roughly two-times FP4 claims are architectural and workload-qualified. They should not be treated as a universal gaming-FPS promise or as a guaranteed result for every model and framework.
Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minutePC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11The bottom line for gamers and creators
Blackwell’s important FP4 innovation is the system around the four-bit value. NVFP4 combines a tiny E2M1 payload with block-level FP8 scales, a global FP32 scale, specialized Tensor Core execution, and software techniques that manage rounding, outliers, and layer sensitivity.
For data centers, that combination targets the cost and memory pressure of large Transformer models. For consumers, the RTX 5090 is the practical Blackwell card to investigate for local AI, but it should be purchased for a specific supported workload rather than for the FP4 label alone. The decisive question is not simply whether a GPU has FP4 hardware; it is whether the model, runtime, and application can use that hardware without unacceptable accuracy or compatibility trade-offs.
Frequently Asked Questions
Is the RTX 5090 equivalent to a B200 or GB200 for FP4 AI?
No. The RTX 5090 is a consumer Blackwell card with 32 GB of GDDR7 and fifth-generation Tensor Cores, while B200, GB200, and DGX systems provide very different memory capacities, interconnects, power envelopes, and enterprise software qualification. The RTX 5090 can be useful for supported local AI workloads, but it is not a desktop replacement for a multi-GPU data-center system.
Does FP4 mean a model uses exactly four bits per parameter?
No. Four bits describes the FP4 payload. NVFP4 also uses local FP8 E4M3 scales, a global FP32 scale, alignment, and sometimes higher-precision layers. Actual memory savings depend on the scale metadata, layout, temporary buffers, and model recipe.
The Tool Desk
Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Will Blackwell FP4 automatically make games faster?
Not by itself. FP4 is primarily aimed at AI matrix operations. A game or application must implement a compatible low-precision workload to benefit. The RTX 5090’s FP4-oriented hardware may help supported AI features, but it does not guarantee a fixed frame-rate gain in every game.
What software is required to use NVFP4?
Check the specific Transformer Engine, CUDA, PyTorch or JAX, TensorRT-LLM, NeMo, Megatron Core, model, and kernel versions together. NVIDIA’s documented NVFP4 path requires Blackwell-class hardware, and training and inference support can differ by implementation and release.
The Bottom Line
Bottom line: Blackwell’s FP4 advantage comes from combining four-bit data with fine-grained scaling and software-managed mixed precision. The RTX 5090 brings relevant capability to desktop users, while B200, GB200, and DGX systems remain enterprise platforms for large-scale AI.




